DevOps / Cloud Engineering

AWS-focused cloud infrastructure, automation, and platform engineering work.

Working on Environment Sync v2

The Environment Sync v2 dialog with tables grouped by site, with sizes, and one subsite unticked

Environment Sync is how developers on Altis copy a site’s database and uploads from one environment to another. You might copy production to staging to reproduce a bug, or to work with real content.

Version 2 made that copy faster and less manual. You can choose which tables and subsites to bring over. URLs are replaced during the import. Post-sync steps run on their own. Every import stays in a history you can come back to. The same sync also runs on your laptop with one command.

Mockups and scope

When I joined the project, I started with exploratory work. I wasn’t sure how it all fit together, so I asked. Were we improving the existing sync, or just adding a few specific features that were requested?

The answer was both.

I think best with tangible things. I also kind of missed flexing my design muscles. So I went ahead and created mockups of what could be improved and how I imagined it would look. It also helped the discussion move forward, since the team had something to comment on.

Here are some of the things that shipped.

Table and subsite selection

Large WordPress multisites can have databases of several hundred GB. A developer working on one subsite doesn’t need all of it.

I built the sync dialog so it loads the source tables and groups them by site, with each site’s domain and table sizes. This one stayed close to the mockup. You can untick whole sites or search for a single table. A later change added size totals for each site and the selection, so you know how much you’re about to copy.

On the backend, I made the sync read the search-replace mapping from the project’s composer.json. You don’t have to remember a separate command afterward. Post-sync hooks let a project run its own steps after a sync, like reindexing Elasticsearch or removing personal data. There’s a toggle to skip them when you only need the data.

Persistent history

Before, an import showed up while it was running. Once it finished, successful or not, it was gone.

I added Previous Imports, so every import stays there now. You can see when it ran, who started it, and its status. If it failed, you can open it and see which step failed and why. The mockup had its own progress view. In the end I reused the log view from deployments so it would feel familiar.

altis-cli sync-local

This one came from an idea at the team retreat. A developer should be able to bring an Altis environment down to their local server with one command.

I built altis-cli app sync-local. It starts a backup, downloads it, and imports the database and uploads. It reads the same search-replace mapping from composer.json as the dashboard, then runs the post-sync hooks. You can sync a single site with --site-id.

Under the hood

Our CTO switched the database import to mydumper and myloader. It’s a lot faster. The dump runs as multiple streams and loads using multiple threads. I added mydumper to backups and exports, and a command to load those dumps on Local Server.

The part I liked most is that search-replace now happens in the pipeline. We forked WordPress VIP’s go-search-replace-mydumper to support mydumper’s stream mode. It rewrites the data as mydumper streams it, then hands it to myloader. Search-replace no longer waits for the whole dump to finish.

Before, the sync used mysqldump. You’d wait for the import to finish, open a sandbox, then run search-replace on the whole database yourself.

Wrapping up

We shipped it in Altis v27 in June. It was nice to follow one feature from a mockup to implementation to documentation. Starting with mockups made the rest easier to talk about.

Exploring and Migrating to OpenResty

/
OpenResty using a Lua routing table to send requests to PHP-FPM sockets for different PHP versions

I have an old CyberPanel instance that still hosts live sites. Some have been running for more than ten years. They’re non-critical, and the server kept working, so I kept putting off maintaining it.

Then php2shell happened. After dealing with it at work, I needed to check my own server too. Most of the sites were on PHP versions that no longer receive security fixes.

I also wanted to try something. A friend mentioned using OpenResty with Lua to route requests to PHP-FPM sockets. I didn’t know the details of their setup, but I was curious if I could do something similar.

Getting the sites working first

I upgraded the sites while they were still on CyberPanel and LiteSpeed. That way, if something broke later, I would have fewer things to check.

Old WordPress installs needed core and plugin updates before they could run on PHP 8. A custom theme had an unquoted constant, a plugin used create_function(), and a small Laravel app needed a framework upgrade.

I also found web shells, a backdoor plugin, and forgotten copies of old sites inside live web roots. The sites were responding fine, but there was a lot I hadn’t been seeing.

One config for the sites

OpenResty is nginx with Lua support. The idea is to let Lua look up the hostname and tell nginx which directory and PHP-FPM socket to use.

Each site has an entry in sites.json:

{
  "example.com": {
    "root": "/home/example.com/public_html",
    "user": "example",
    "kind": "php",
    "cert": "example.com",
    "https": true,
    "php": "8.4"
  }
}

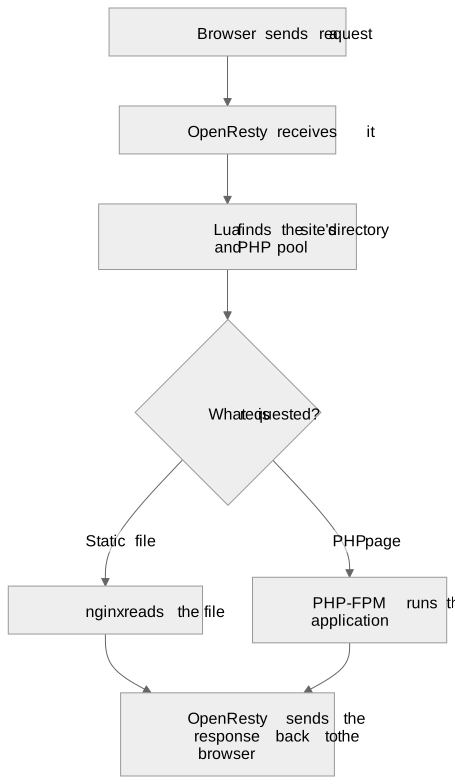
Lua keeps the routes in memory. It selects the certificate during the TLS handshake, then uses the request’s hostname to choose the site. nginx serves static files directly and passes PHP requests to the right FPM socket.

Request lifecycle from the browser through OpenResty and back

Each Linux account gets its own PHP-FPM pool. Sites under the same account still share permissions, so I moved the contracts app into its own user and pool. The pools use ondemand so workers stop when idle. Useful on a small VPS.

The config also supports choosing a PHP version per site, though I’ve only installed and tested 8.4 so far. Databases mostly stayed as they were: local MariaDB, and SQLite for the contracts app.

CyberPanel and LiteSpeed are gone now. Lua looks up the hostname, nginx serves the files, and PHP-FPM runs the application. I can follow a request from its hostname to a directory and a PHP socket. Pretty happy to have this working.

Live configuration updates

I wanted to add sites or change their PHP sockets without reloading OpenResty.

A small root-owned publisher checks sites.json and the certificate files, validates the changes, and writes a complete snapshot. The Lua workers pick it up and replace their in-memory routes and certificates together. The snapshot is private because it contains TLS keys; the PHP accounts can’t read it.

This implementation uses one-second polling in the publisher and workers, so updates normally take about two seconds. Requests use the in-memory tables. If an update is invalid, the last valid configuration keeps working.

I tested adding and removing a hostname, switching PHP sockets, and replacing a certificate. The OpenResty master and worker process IDs stayed the same throughout.

Next steps

  • Try Linux inotify events instead of polling, so configuration changes can notify the workers directly.
  • Use OpenResty as a reverse proxy across my homelab sites, with a primary and secondary site. Start with manual failover.
  • Move files and uploads to NFS shares with replication between sites.
  • Add MySQL primary/replica replication.
  • Keep PHP-FPM workers warm while retaining separate pools per account. More RAM, but less startup delay.

For next time!

Dealing with php2shell

/
Requests passing through a WAF to PHP, with exploit attempts blocked

When John Blackbourn alerted the team about the leaked PHP vulnerability, I knew where to make the recommended configuration change. But I also knew that rolling it out across our infrastructure would take time.

That was on October 21, 2026. The vulnerability could allow remote code execution without authentication. It was later disclosed as CVE-2026-109618 and CVE-2026-109619, and became known as php2shell. The disclosure had been moved forward by a day, and a proof of concept was already circulating.

We didn’t have the complete picture yet.

Working with incomplete information

The leak pointed to PHP’s session upload-progress feature. One of the recommendations was to disable session.upload_progress.enabled.

The official PHP security releases weren’t scheduled until 14:00 UTC, more than ten hours away. Upgrading wasn’t an option yet. We needed to reduce our exposure until then.

Our infrastructure uses shared base images and a controlled release process, so even a small config change goes through several steps before it reaches production. I estimated around two hours (took longer).

With a proof of concept already out there, I started thinking about what else we could do in the meantime.

A faster mitigation at the WAF level

I suggested a platform-wide WAF rule to block requests matching the known exploit pattern. A WAF rule can be deployed without touching the application runtime, so we wouldn’t have to wait for every environment to get the PHP change.

This was not a small change. A WAF rule at the platform level sits in front of every site we host. If I got it wrong, it wouldn’t break one site. It could break all of them at once.

So instead of blocking a whole class of requests, which could break normal WordPress functionality, we targeted the specific pattern we understood.

I tested it in staging. It blocked the exploit requests while file uploads and editor saves kept working. But staging is not production. I tested as much as I could, and there was still no way to be sure it wouldn’t block legitimate traffic.

I also knew it could be bypassed. It was never meant to be the fix, just something to reduce exposure while we waited.

Waiting felt riskier than shipping, so I made the call and rolled it out to production.

Watching the traffic

I checked the WAF logs every few minutes for blocked requests and possible false positives. My own test requests were blocked first. Later, real traffic matching the pattern started showing up, and the WAF was blocking it.

That was encouraging, but a blocked request doesn’t mean an exploit was prevented. It only meant requests matching our rule were stopped. At that point, I could say our mitigation was working against the pattern we knew about. I couldn’t say the platform was fully protected.

Meanwhile, the PHP change

The image builds ran into a problem I didn’t expect. An external service we use to install PHP extensions was having availability issues, and builds failed intermittently. A simple config change, delayed by something outside our control.

After retries, the builds succeeded and we verified the setting:

session.upload_progress.enabled => Off

Then it rolled out through our normal deployment process. Unlike the WAF rule, this disabled the affected feature itself.

It also made me think about our release process. Pinning dependencies and runtime versions makes deployments reproducible, which is usually a good thing. But during an incident, every extra step is time between a fix existing and that fix reaching production.

What the advisory revealed

At around 14:00 UTC, the PHP team published the full disclosure and fixes. There were two critical vulnerabilities, both rated 9.2 under CVSS v4.0:

  • CVE-2026-109619: RCE involving stale global state. Disabling session.upload_progress.enabled was one of the recommended temporary mitigations.
  • CVE-2026-109618: RCE involving out-of-memory corruption. We didn’t know about this one from the leak, and nothing we had done addressed it.

The advisory was clear:

There are no complete mitigations, updating is the only safe choice.

The fixes shipped in PHP 8.5.12, 8.4.27, 8.3.36, and 8.2.35, and the team upgraded PHP across all customer environments.

We acted on what we knew, but it turned out we only knew half of it. I’m glad we had a way to add a layer of protection fast, and that we never treated it as the fix.

Fixing Auto-Deploy: From a Polling Cron to Event-driven Deploys

Before and After auto-deploy architecture

Auto-deploy is a feature where if there’s a new build image, it will deploy it… automatically. Customers started to occassionally report that auto-deploy isn’t working on their environment. The usual fix was to restart the cron job.

That only goes so far.

I didn’t know how it works before picking the issue up. I learned that there was a cron job called schedule_deployments. The way it’s implemented is it calls the AWS API for each environment to 1) fetch the latest ECR image and 2) compare the deployed image in ECS, then trigger a deploy if it does not match. That meant two API calls per environment for all environments. I started understanding why it was working fine before, but not anymore as we grew.

My initial solution was to optimize the current approach

CodeBuild already posts an app package manifest to our dashboard at the end of every build (from another feautre). I thought I could piggyback on that event and store a new_build flag on the environment when it triggers. I would then add a filter in schedule_deployments() to only process environments with new builds.

It was working. Fewer API calls, less chance of failing. PR ready for review.

The question that came up in the review was: if we already know when there is a new build, why are we still polling?

It made a lot of sense, and made me wonder why I restricted myself to optimizing only.

The final fix

New PR created, now with the fan-out approach. I removed schedule_deployments entirely. In its place, a new_build_created hook that triggers when the app package manifest comes in. From this hook, we check if auto-deploy is enabled, and if it is we schedule a deploy.

As a side-effect, this also fixed a bug in our auto-deploy logic where if a customer rolled back to an older build image, it would be reverted back again to latest image on the next cron run (oops).

Obvious in hindsight, of course. What’s important is there have been no auto-deploy complaints since this shipped to production.

Another fun, satisfying thing I was able to work on.

Passed AWS Solutions Architect Professional & DevOps Engineer Professional

/
AWS Solutions Architect Professional and DevOps Engineer Professional badges

I passed AWS Solutions Architect Associate last December. At the end of that post I mentioned I’d pursue the Professional tier next. Passed Solutions Architect Professional on February 15. Then took DevOps Engineer Professional on March 19.

One day of prep for each (the day before). I mostly banked on production experience. Most of what came up in the exam, I’ve encountered at work in some form.

SAP felt like a more comprehensive version of SAA. I finished in two hours out of three.

DOP was a lot harder than I expected. It was less about architecture and more on the specific behavior of AWS services. A lot of EKS questions came up and we don’t use Kubernetes at work. I guessed on those. I flagged 30 questions total. I went back and re-read each one carefully. I used the whole three hours, super exhausted. I was honestly bracing myself for retaking it. Luckily, I passed.

I joined my current role without even knowing what Terraform was. I only knew web development and LAMP stacks. I always had this doubt at the back of my mind whether I’m actually a cloud engineer or just got lucky landing the role. SAA felt too easy and didn’t really move the needle on that.

DOP being tough and still passing did. It’s not something someone could LLM their way around. Almost everything I relied on was things I actually learned on the job. That’s what made it feel different. I feel much more genuine with my title now. More confident with my voice. These exams showed me I can reason out architectural design decisions.

I don’t plan to take more certifications anytime soon. But if I ever did, it’d be CKA or CKAD. The amount of EKS questions on both exams made me realize how much I’m missing there. ECS is what we use at work but it’s AWS-only. Kubernetes is cloud-agnostic, can run anywhere including self-hosted, and it’s almost synonymous with DevOps at this point.

I want to widen the net.

Passed AWS Solutions Architect Associate

/
AWS Certified Solutions Architect - Associate certificate

So, I finally took and passed AWS SAA-C03. 4 years of procrastination, 2 exam reschedules, and 3 days of actually soaking my head in SAA topics.

As most of the things in my life, I spent more time stressing for it, and when I actually pushed thru working on it turned out to be easier than expected.

I spent 40 mins out of the 130 mins allowed. There were about 10 questions I had absolutely no idea about. The rest were fairly straightforward. The questions I did not know weren’t like some architecture questions, more on familiarity on what a service actually does. Anything CloudFront, S3, EC2, ECS, Lambda, VPC I was able to answer confidently. These are services we actually run in production. Having real hands-on experience helped a lot.

I think getting a certification did its purpose, filling in gaps with my AWS knowledge on things we don’t use but actually could be useful. Fun to learn about different storage solutions and appropriate uses. Fun to learn about AWS Org.

The exam felt unusually easy. It didn’t remove my impostor syndrome of being a qualified cloud engineer. Instead, it clarified that the gaps are less about fundamentals and more about reasoning across larger systems. I decided to pursue the more tougher exam Solutions Architect – Professional (scheduled Q1 next year).

Let’s see where this goes.

Related: Passed AWS Solutions Architect Professional & DevOps Engineer Professional.

Shipping Log Shipping: From Spike to Customer Environment

/
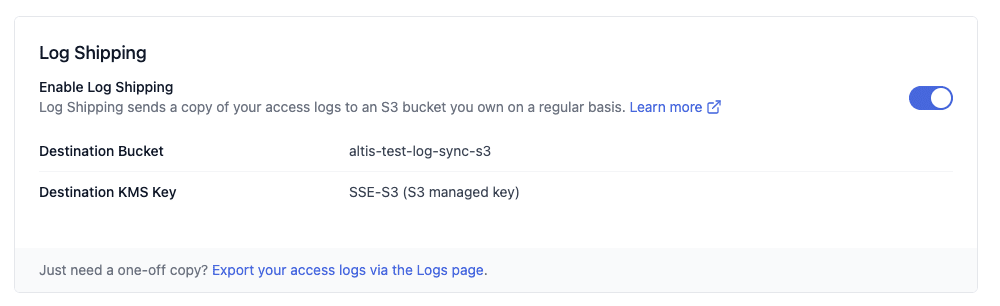
Log Shipping feature in the customer dashboard

Log Shipping lets customers automatically ship a copy of their access logs to an S3 bucket they own. Small feature, but it touched every layer of the stack. I had a chance to work on every part of it.

Spike: picking the right approach

Before writing any code, we do a spike to research and decide the best approach. For Log Shipping, two options came up:

  • Option 1: A Lambda function that polls and copies S3 objects on a schedule every minute.
  • Option 2: S3 Event Notifications that trigger a Lambda when new objects are added.

Option 2 was the right call. No polling means fewer API calls, better scaling, and a cleaner architecture. The cost difference was negligible.

Infrastructure

The bulk of the work. Log Shipping is primarily an infrastructure feature. S3 event notifications, Lambda, IAM permissions, and the wiring between them. It was implemented as a Terraform module so it can be enabled or disabled per customer environment without touching the core stack.

Backend API

Once the infrastructure was in place, the feature needed to be surfaced through the API. The backend integrates with AWS and reads from Terraform state to get the configuration details of an environment. Whether log shipping is enabled, the destination bucket, and the encryption key in use.

Frontend (React)

The API data gets displayed in the customer-facing dashboard. This is what the customer actually sees and interacts with. My background in web development came in useful here.

Documentation

The feature shipped with updated customer-facing documentation describing what Log Shipping does and how to enable it. Documentation is part of shipping, not an afterthought.

Rollout

After merging, the rollout followed a set sequence. Infrastructure release, backend deploy, frontend deploy, then a change request to enable the feature in a specific customer environment. The last step involved coordinating with the customer directly to confirm their destination bucket and encryption preferences.

Finding a Way Around CloudFront origin_shield Drift in Terraform

Every Terraform plan flag a change in our CloudFront distribution (even when nothing is actually changing).

The issue was origin_shield. When it is disabled, AWS drops it from the response. Terraform sees it missing and adds it back with enabled = false every run.

So every run you would see CloudFront being changed. Big deal because it’s the CDN, misconfiguration could bring down a site. What ends up happening is we always had to inspect the change.

The obvious fix was to make the block dynamic so it only appears when origin shield is actually enabled.

dynamic "origin_shield" {
  for_each = var.enable_cloudfront_origin_shield ? [1] : []
  content {
    enabled              = var.enable_cloudfront_origin_shield
    origin_shield_region = data.aws_region.current.name
  }
}

Drift was gone, plans were clean. But then I found the other side of the problem.

If origin shield was enabled, then later disabled, Terraform would plan to remove the block. The plan looked right. Apply ran. Nothing happened. Origin shield stayed on in the AWS Console because the provider simply removed enabled = true but AWS needed an explicit enabled = false and we are back to the original problem.

We filed a bug report in April 2022. Three years passed, it’s still open.

I can’t fix the provider, but I really really wanted a clean plan/apply in our infrastructure.

I figured, I could work around it by using a null_resource that only exists when origin shield is disabled. When it runs, it calls the AWS API directly and forces OriginShield.Enabled = false.

resource "null_resource" "cloudfront_origin_shield_disable" {
  count = var.create_cloudfront == "yes" && !var.enable_cloudfront_origin_shield ? 1 : 0

  triggers = {
    enable_origin_shield = var.enable_cloudfront_origin_shield
    distribution_id      = aws_cloudfront_distribution.default[0].id
    script_hash          = filemd5("${path.module}/bin/disable-cloudfront-origin-shield.sh")
  }

  provisioner "local-exec" {
    command = "${path.module}/bin/disable-cloudfront-origin-shield.sh ${aws_cloudfront_distribution.default[0].id} wordpress"
  }

  depends_on = [aws_cloudfront_distribution.default]
}

The null_resource only runs on the transition from enabled to disabled. It fetches the current config, exits early if origin shield is already off, and only patches it when needed.

CLOUDFRONT_CONFIG=$(aws cloudfront get-distribution-config --id "$DISTRIBUTION_ID" --output json)
ETAG=$(echo "$CLOUDFRONT_CONFIG" | jq -r '.ETag')
DISTRIBUTION_CONFIG=$(echo "$CLOUDFRONT_CONFIG" | jq '.DistributionConfig')

jq --arg origin_id "$ORIGIN_ID" '
  .Origins.Items = [
    .Origins.Items[] |
    if .Id == $origin_id then
      .OriginShield.Enabled = false
    else
      .
    end
  ]
' <<< "$DISTRIBUTION_CONFIG" | aws cloudfront update-distribution \
    --id "$DISTRIBUTION_ID" \
    --distribution-config /dev/stdin \
    --if-match "$ETAG"

I distinctly remember being very satisfied that it’s working after spending couple of hours on this bug. Every re-run took minutes! When it finally worked, I felt so relieved.

The bug is still open, but at least our plans are finally clean.

Related: Why ECS Task Definitions Kept Changing on Every Apply.

Why ECS Task Definitions Kept Changing on Every Apply

/

Every Terraform apply was creating new ECS task definition revisions even when nothing had actually changed. Our test environment had accumulated 17,000 task definitions. ECS task definitions are tracked by AWS Config, so this was quietly contributing to increased costs.

In AWS ECS, a task definition is a blueprint that describes how a container should run — what image to use, environment variables, resource limits, health checks, and so on. Every time Terraform sees a difference between what it expects and what AWS has, it creates a new revision. When that happens on every apply with no real change, something is off.

Finding the root cause

The way to debug this is to compare what Terraform has in state against what the AWS API actually returns. Pull the task definition from Terraform state and diff it against the output of aws ecs describe-task-definition. The differences tell you exactly what Terraform thinks it needs to change.

Two causes came up.

Environment variable ordering. AWS reorders environment variables alphabetically when storing a task definition. Terraform was building the environment variable list using merge(), a built-in function that combines maps but does not guarantee key order. On each plan, the order could differ from what AWS had stored, so Terraform saw a change that wasn’t really there.

Missing properties in the container templates. Some optional fields were absent from the JSON templates we used to define containers. AWS fills these in with default values and includes them in the API response. When Terraform compared its template against the API response, it saw those extra fields as additions it needed to remove — which triggered another replacement.

Fields like healthCheck.interval, healthCheck.retries, healthCheck.timeout, systemControls, mountPoints, and portMappings all fell into this category.

The fix

For environment variable ordering, the fix is to sort the keys explicitly before building the list so Terraform and AWS always agree on the order.

locals {
  merged_env_vars = merge(local.php_environment_json, var.extra_ecs_env_vars)
  php_environment_ecs = [
    for k in sort(keys(local.merged_env_vars)) : {
      name  = k
      value = local.merged_env_vars[k]
    }
  ]
}

For the missing properties, the fix is to add them explicitly to the container JSON templates to match what AWS returns. Once both sides agree, Terraform stops seeing phantom changes.

After both fixes, running the plan twice in a row showed no changes on the second run.

Related: Reducing Terraform Drift in Production and Finding a Way Around CloudFront origin_shield Drift in Terraform.

Reducing Terraform Drift in Production

/
Terraform plan showing no changes

Our Terraform runs were showing changes on every apply, even when nothing had actually changed. When the plan is always noisy, it’s easy to miss a change that actually matters.

I picked this up on my own during spare time. Originally thinking one drift fix per sprint. Seeing the reduced change set gave me a dopamine hit and I just kept going until there were none left.

Five sources of drift across CloudFront, ECS, Secrets Manager, and Terraform provider bugs. All cleaned up.

The fixes

Make origin_shield dynamic

  • When origin_shield is disabled on a CloudFront distribution, AWS removes it from the refreshed state entirely, causing drift on every plan
  • Made the block dynamic so it is only included when enabled
  • There was a secondary provider bug when disabling via a dynamic block that needed its own workaround

Fix null_resources

  • timestamp() in triggers caused Terraform to show changes every run since the value always differs
  • Moved script execution to external data sources to remove drift while still running scripts every apply
  • Split dependency installation into a separate null_resource so it only runs once

Fix task definitions

  • Every apply created new ECS task definition revisions even with no real changes. Task definitions are tracked by AWS Config so this had a cost implication
  • Identified mismatches in environment variable ordering and missing optional properties by comparing Terraform state with the AWS API response
  • Standardized ordering and completed missing fields in the template
  • Full write-up

Webhook secrets

  • An AWS provider issue caused webhook secrets to always show as changed
  • Added ignore_changes for the secret value

Resources not managed by Terraform

  • Some resources existed in AWS but were intentionally not managed by Terraform, which resulted in drift
  • Added the relevant attributes to ignore_changes

This has been shipped and running across all our environments for a couple of months, nothing broke.

This was also a good stress test of how well I understand our infrastructure.

It was a fun exercise.

New Role: Cloud Engineer at Human Made

/
The red Human Made company logo on a white background.

I recently joined Human Made as a Cloud Engineer. The application process spans a few weeks and I was super anxious with the whole thing. I was actually bracing myself for rejection. But when offer has finally been made, I was jacked to the tits!

This is a big win and exciting for me for multitude of reasons:

Culture

Start with trust, and be trustworthy

The whole company values aligns with mine and makes a lot of sense. I strive in a trusting environment. I naturally give my best to people who supports me. The company have a big focus on the well-being of its people (also called Humans).

HR policies reflects company values. On my first day: 1) they provided more than adequate equipment 2) health care coverage to me and all my dependents 3) pro-rated paid time-off that I’m required to use, and other things that just shows how much they care.

Working with top-notch talent

I couldn’t believe it when I realized that our Director of Product (my boss) was the one who created WP-API.

I distinctly remember getting really excited when it first launched because I was working on a WP project that was AJAX/jQuery-heavy. The code base started to felt hacky the more features were implemented. When I tried WP-API (even though it was still in beta) together with AngularJS, development started to become enjoyable and easier to maintain. It made my life and that project’s code so much nicer!

I feel small around other Humans because of sheer amount of experience everybody have, which is a good thing. Feeling small only expands my opportunity of growth. Observing how other people do things makes me realize gaps in my knowledge that I need to fill-in. I also have access and learn from them. This position will only accelerate my growth.

New career path

I’m coming from full-stack web development. I’ve been doing this for more than a decade. However, I’ve always been drawn to servers, networking, and automation ever since I tried sharing our dial-up connection, for two computers, using a crossover LAN cable when I was a kid.

Applying required me to do a trial. The trial involves troubleshooting a broken stack. They provide all the documentation and access to AWS console. I was told that I don’t have to fix it but I need to write down my troubleshooting steps. I had so much fun doing the trial. It took me 4 hours of intense focus and frustration, but the satisfaction of finally making it work was just priceless.

I still have a lot of gaps in DevOps skills. I’m planning my next few years focusing and honing those to give more value back to the company. And also have fun learning along the way.

Validation of my current skillset

”There’s a deep satisfaction when you know how valuable you are, and the world agrees.” - Derek Sivers

I try not to seek validation. But it just feels good to know that my skills is on par with first-world talent.

#

Despite emphasis on my skills, I still largely credit luck (being blessed) on how I landed in Human Made. My skills only maximized my chance, but overall I just got incredibly lucky (blessed).